
Web scraping tutorials
Short, practical tutorials. Each one solves one job with the scrape.land API and shows the exact request, the JSON that comes back, and what it costs. The screenshots are real output, captured by running each request against sites built for scraping practice. The full reference lives in the docs.
Getting startedNo-code toolsE-commerce and pricesLeads and local businessesJavaScript and browsersTunneling and IPsAI extractionUse casesIntegrationsPlans and scale
Getting started
-
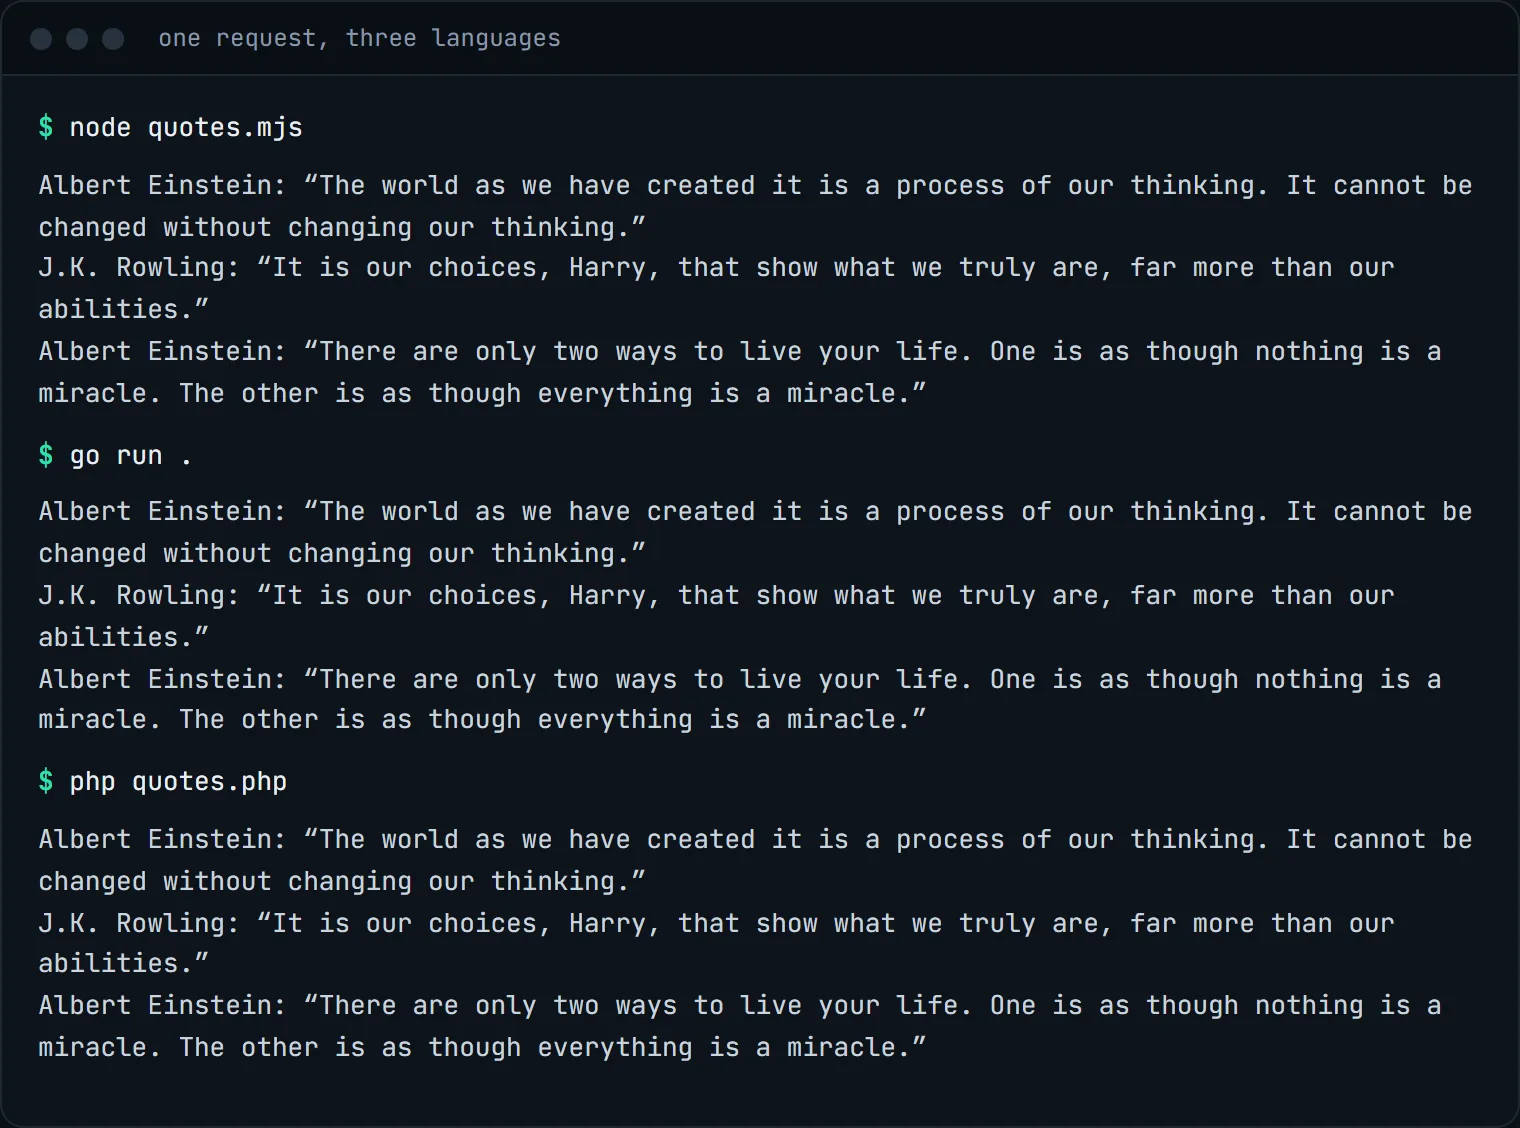 How to scrape a web page with Node.js, Go and PHP
One extraction request written three times, in Node.js, Go and PHP, each run for real against a practice site.
-
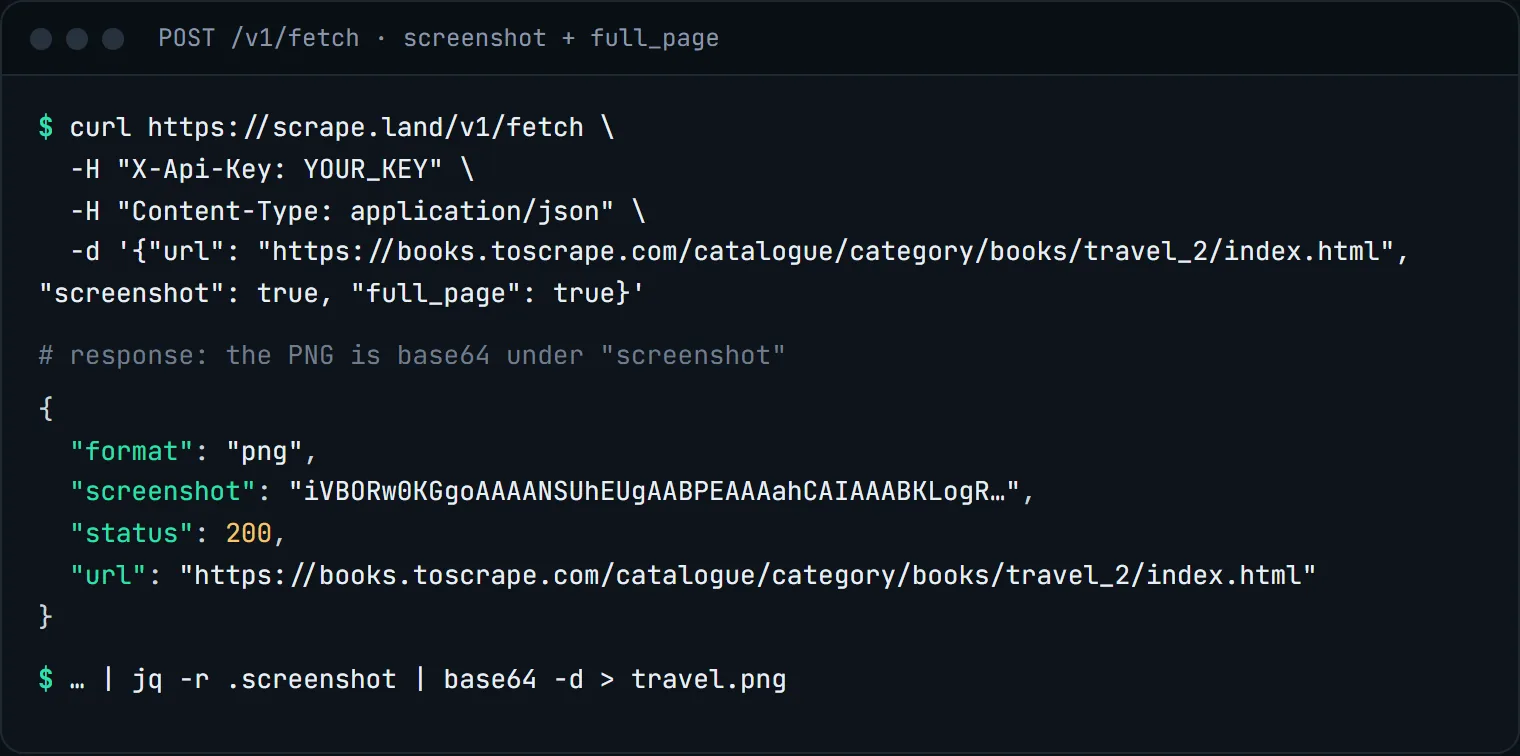 How to take a full-page screenshot of any URL
Get a PNG of the viewport or the whole scroll height with one call, and click a cookie banner away first.
-
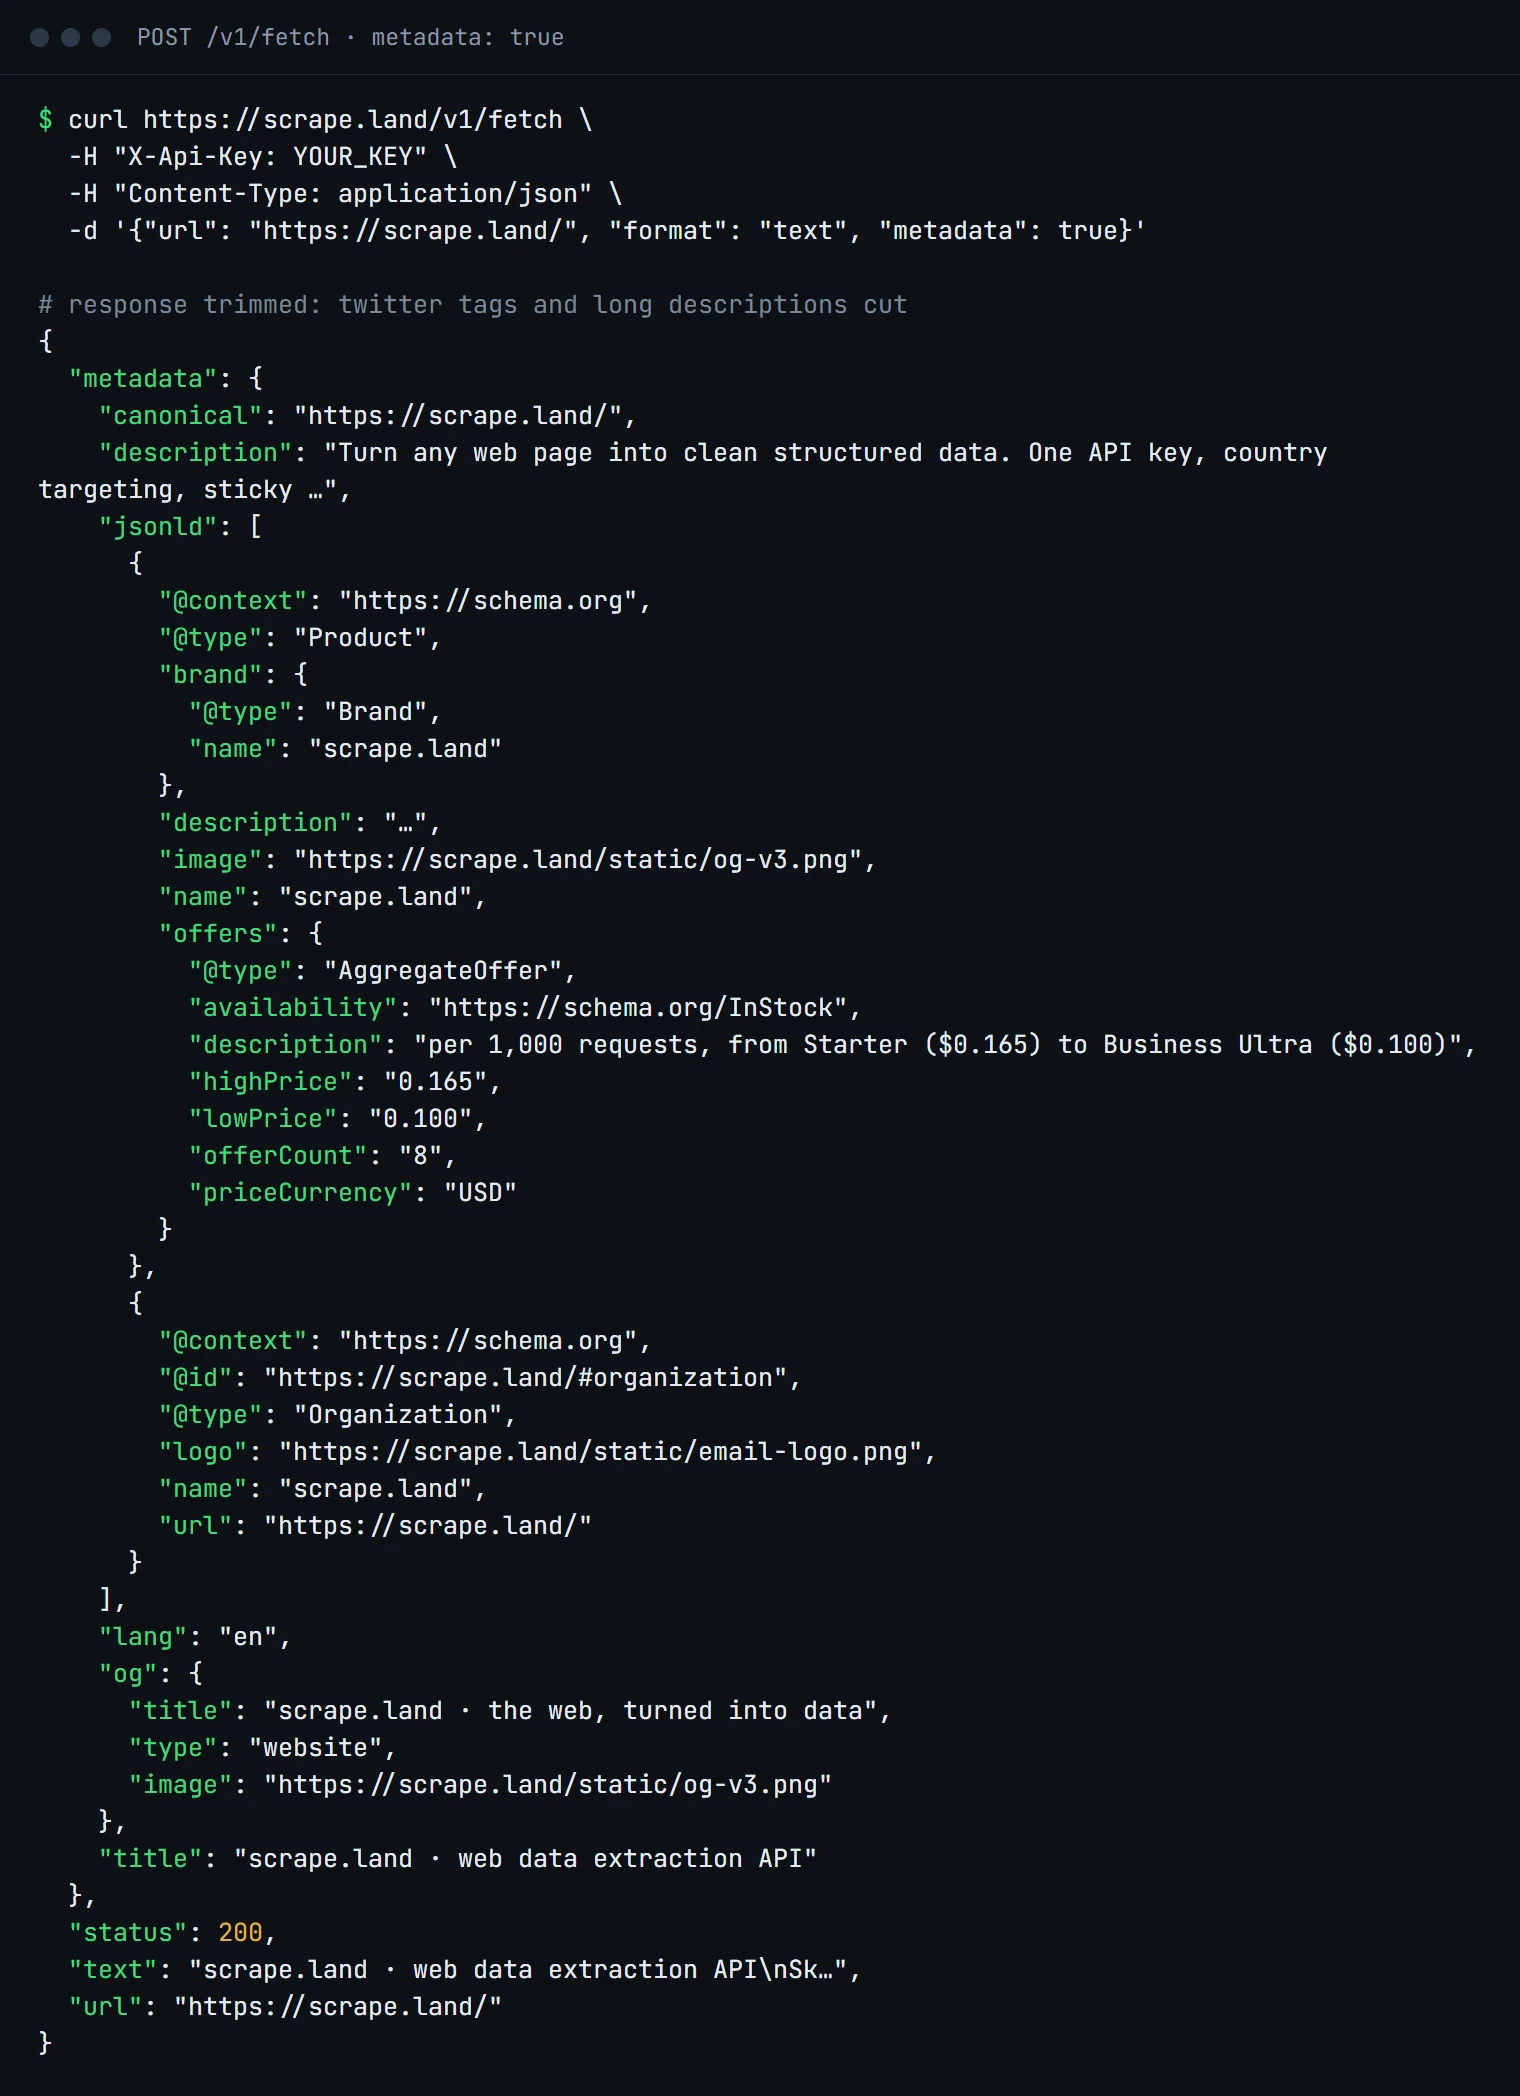 How to get page metadata and JSON-LD from any URL
Title, description, canonical, OpenGraph tags and parsed schema.org JSON-LD in one call, no selectors.
-
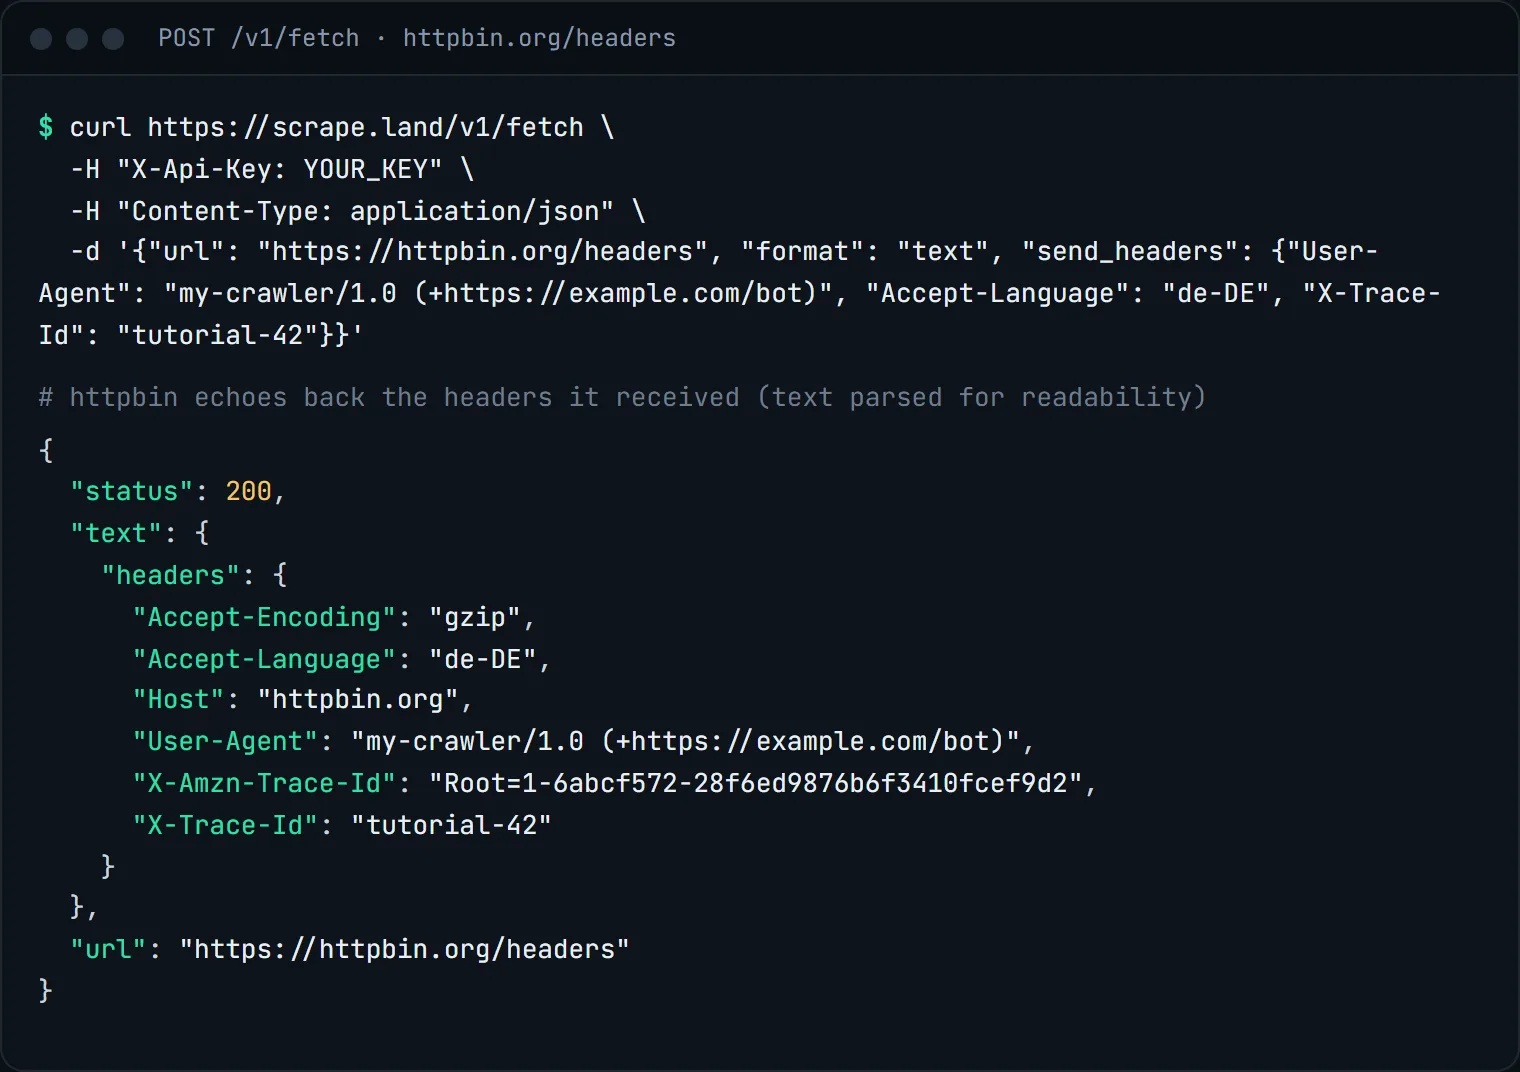 How to send custom headers and cookies with a scrape
Forward a custom User-Agent, language or auth header and a Cookie header, and read the response headers back.
-
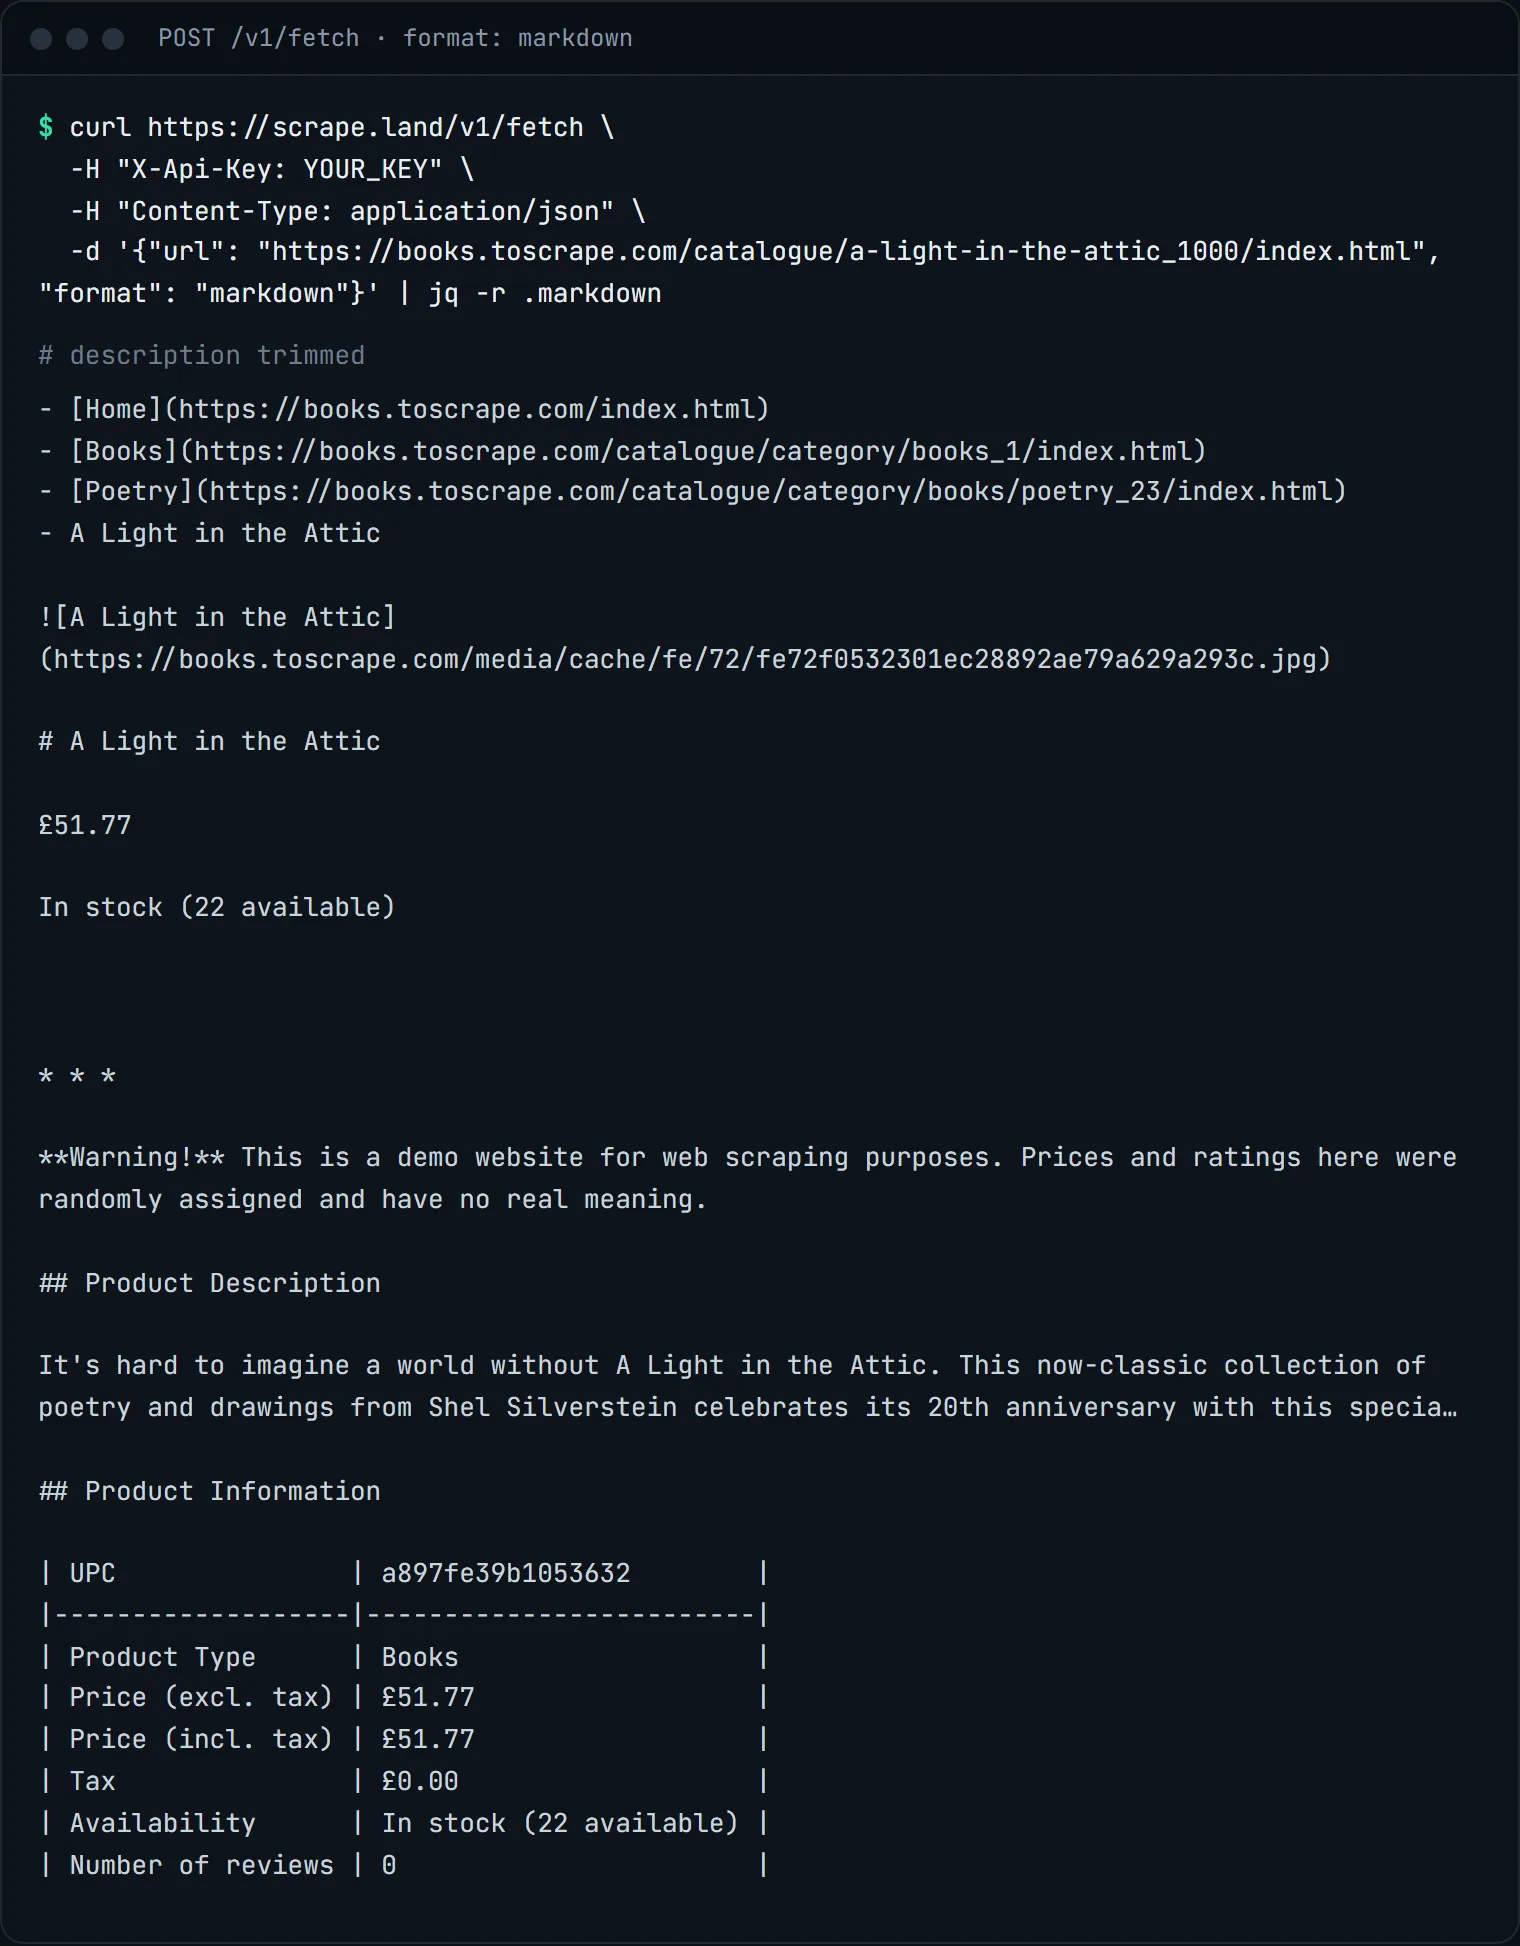 How to get clean Markdown from any page for an LLM
Turn any web page into clean Markdown for an LLM prompt or a RAG index, with boilerplate stripped and links resolved.
-
 How to scrape your first web page with curl
From no account to a scraped page in a minute: one curl call, what comes back, and Markdown or text output.
-
 How to extract fields with CSS selectors
Text, attributes, lists and groups of objects with CSS selectors, plus how null and field_errors differ.
-
 How to handle scraping errors and retries in Python
Which errors to retry, which to fix, what is billed, and a Python helper with timeouts, backoff and logging.
-
 How to find every page of a site from its sitemap
Read robots.txt and sitemaps (including indexes) through the API, list every URL in Python, then extract politely.
-
 How to extract data with XPath selectors
Use XPath when CSS falls short: match by text, read the cell next to a label, and climb from a name to its block.
No-code tools
-
 How to build a local lead list without code
Pick a business type and a city in the dashboard, filter the map, find emails and download a CSV.
-
 How to find emails on company websites without code
Lead Finder turns a list page or a list of websites into public emails, phones and social links.
-
 How to extract a table from many pages without code
Paste page URLs into the dashboard, describe the columns in plain words, and download one row per page as a CSV.
E-commerce and prices
-
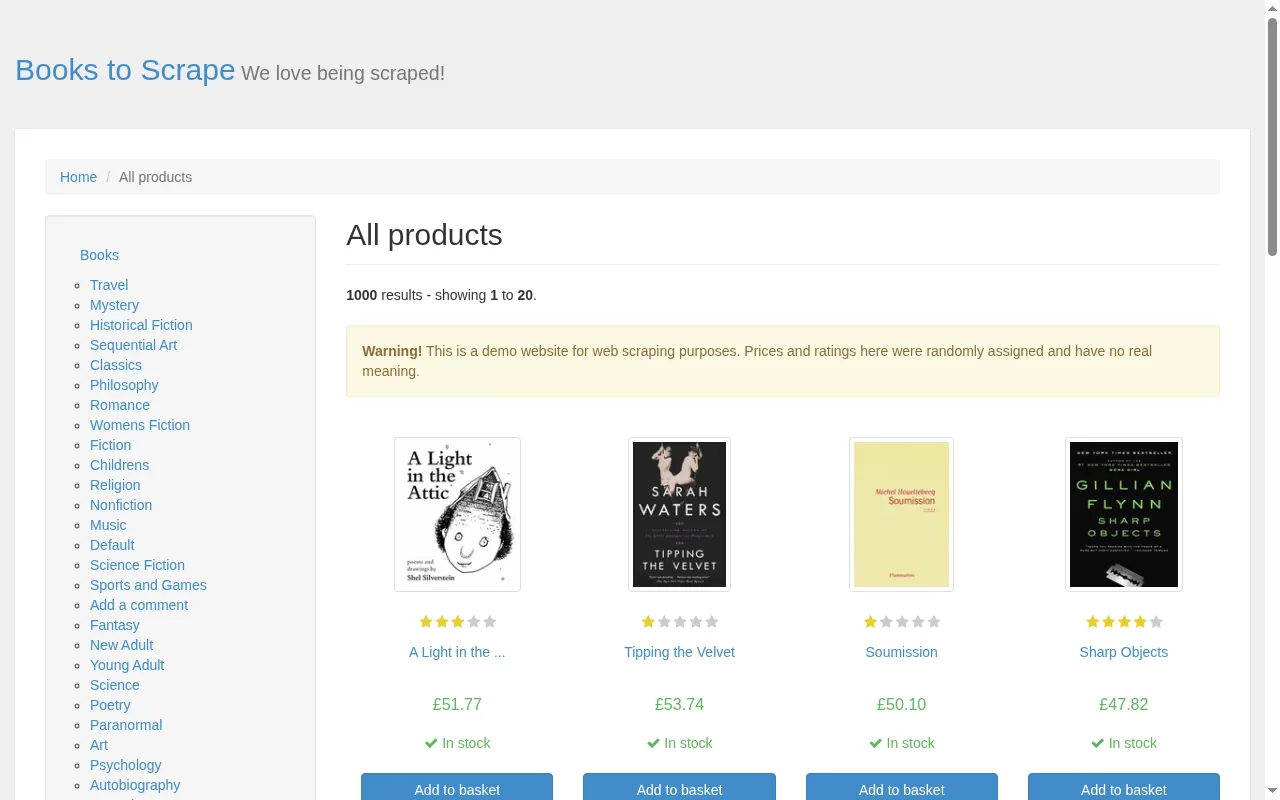 How to scrape a product catalog with pagination
Read each page's products and its next-page link in one call, then loop client-side in Python and save a CSV.
-
 How to extract product prices into a spreadsheet
Read name and price from product pages with CSS selectors or a plain-English prompt, and write them to a CSV.
-
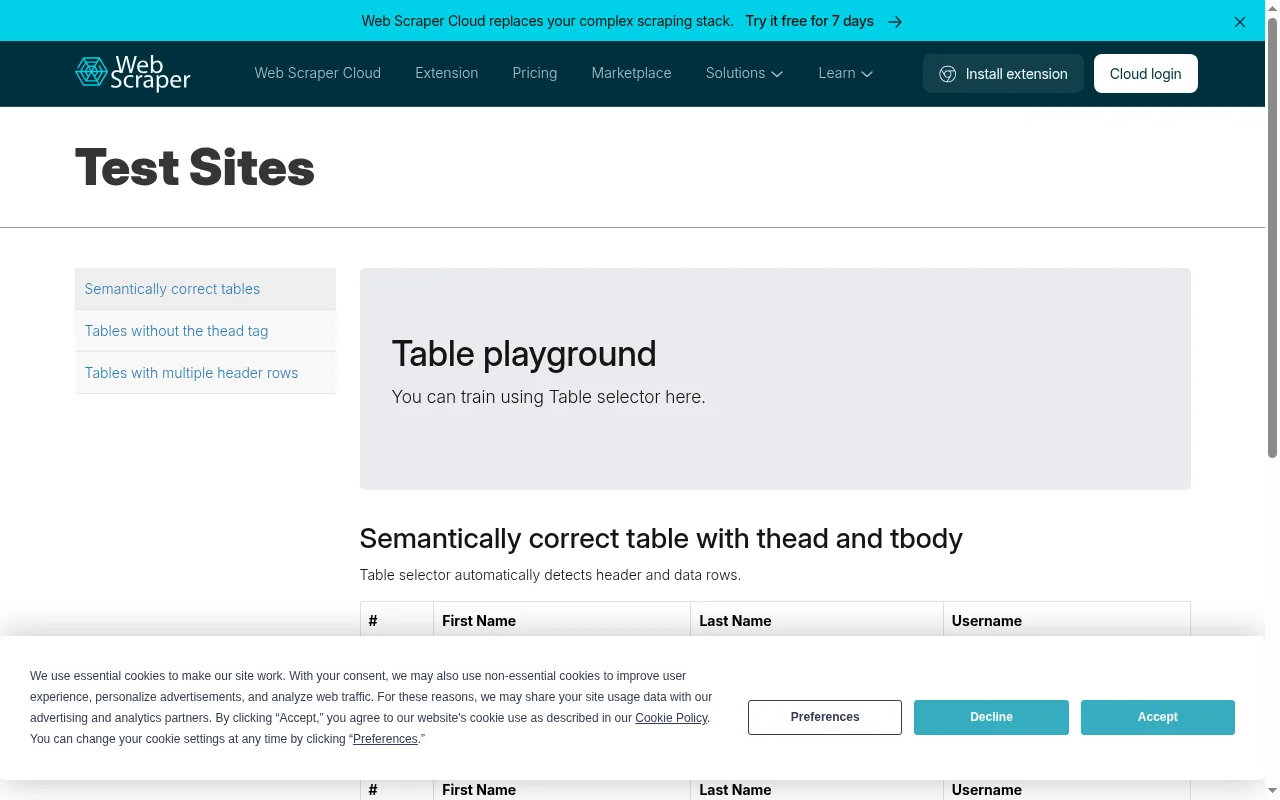 How to extract HTML tables into CSV
Get one object per table row with a nested selector, handle key-value spec tables, and write the rows to CSV.
-
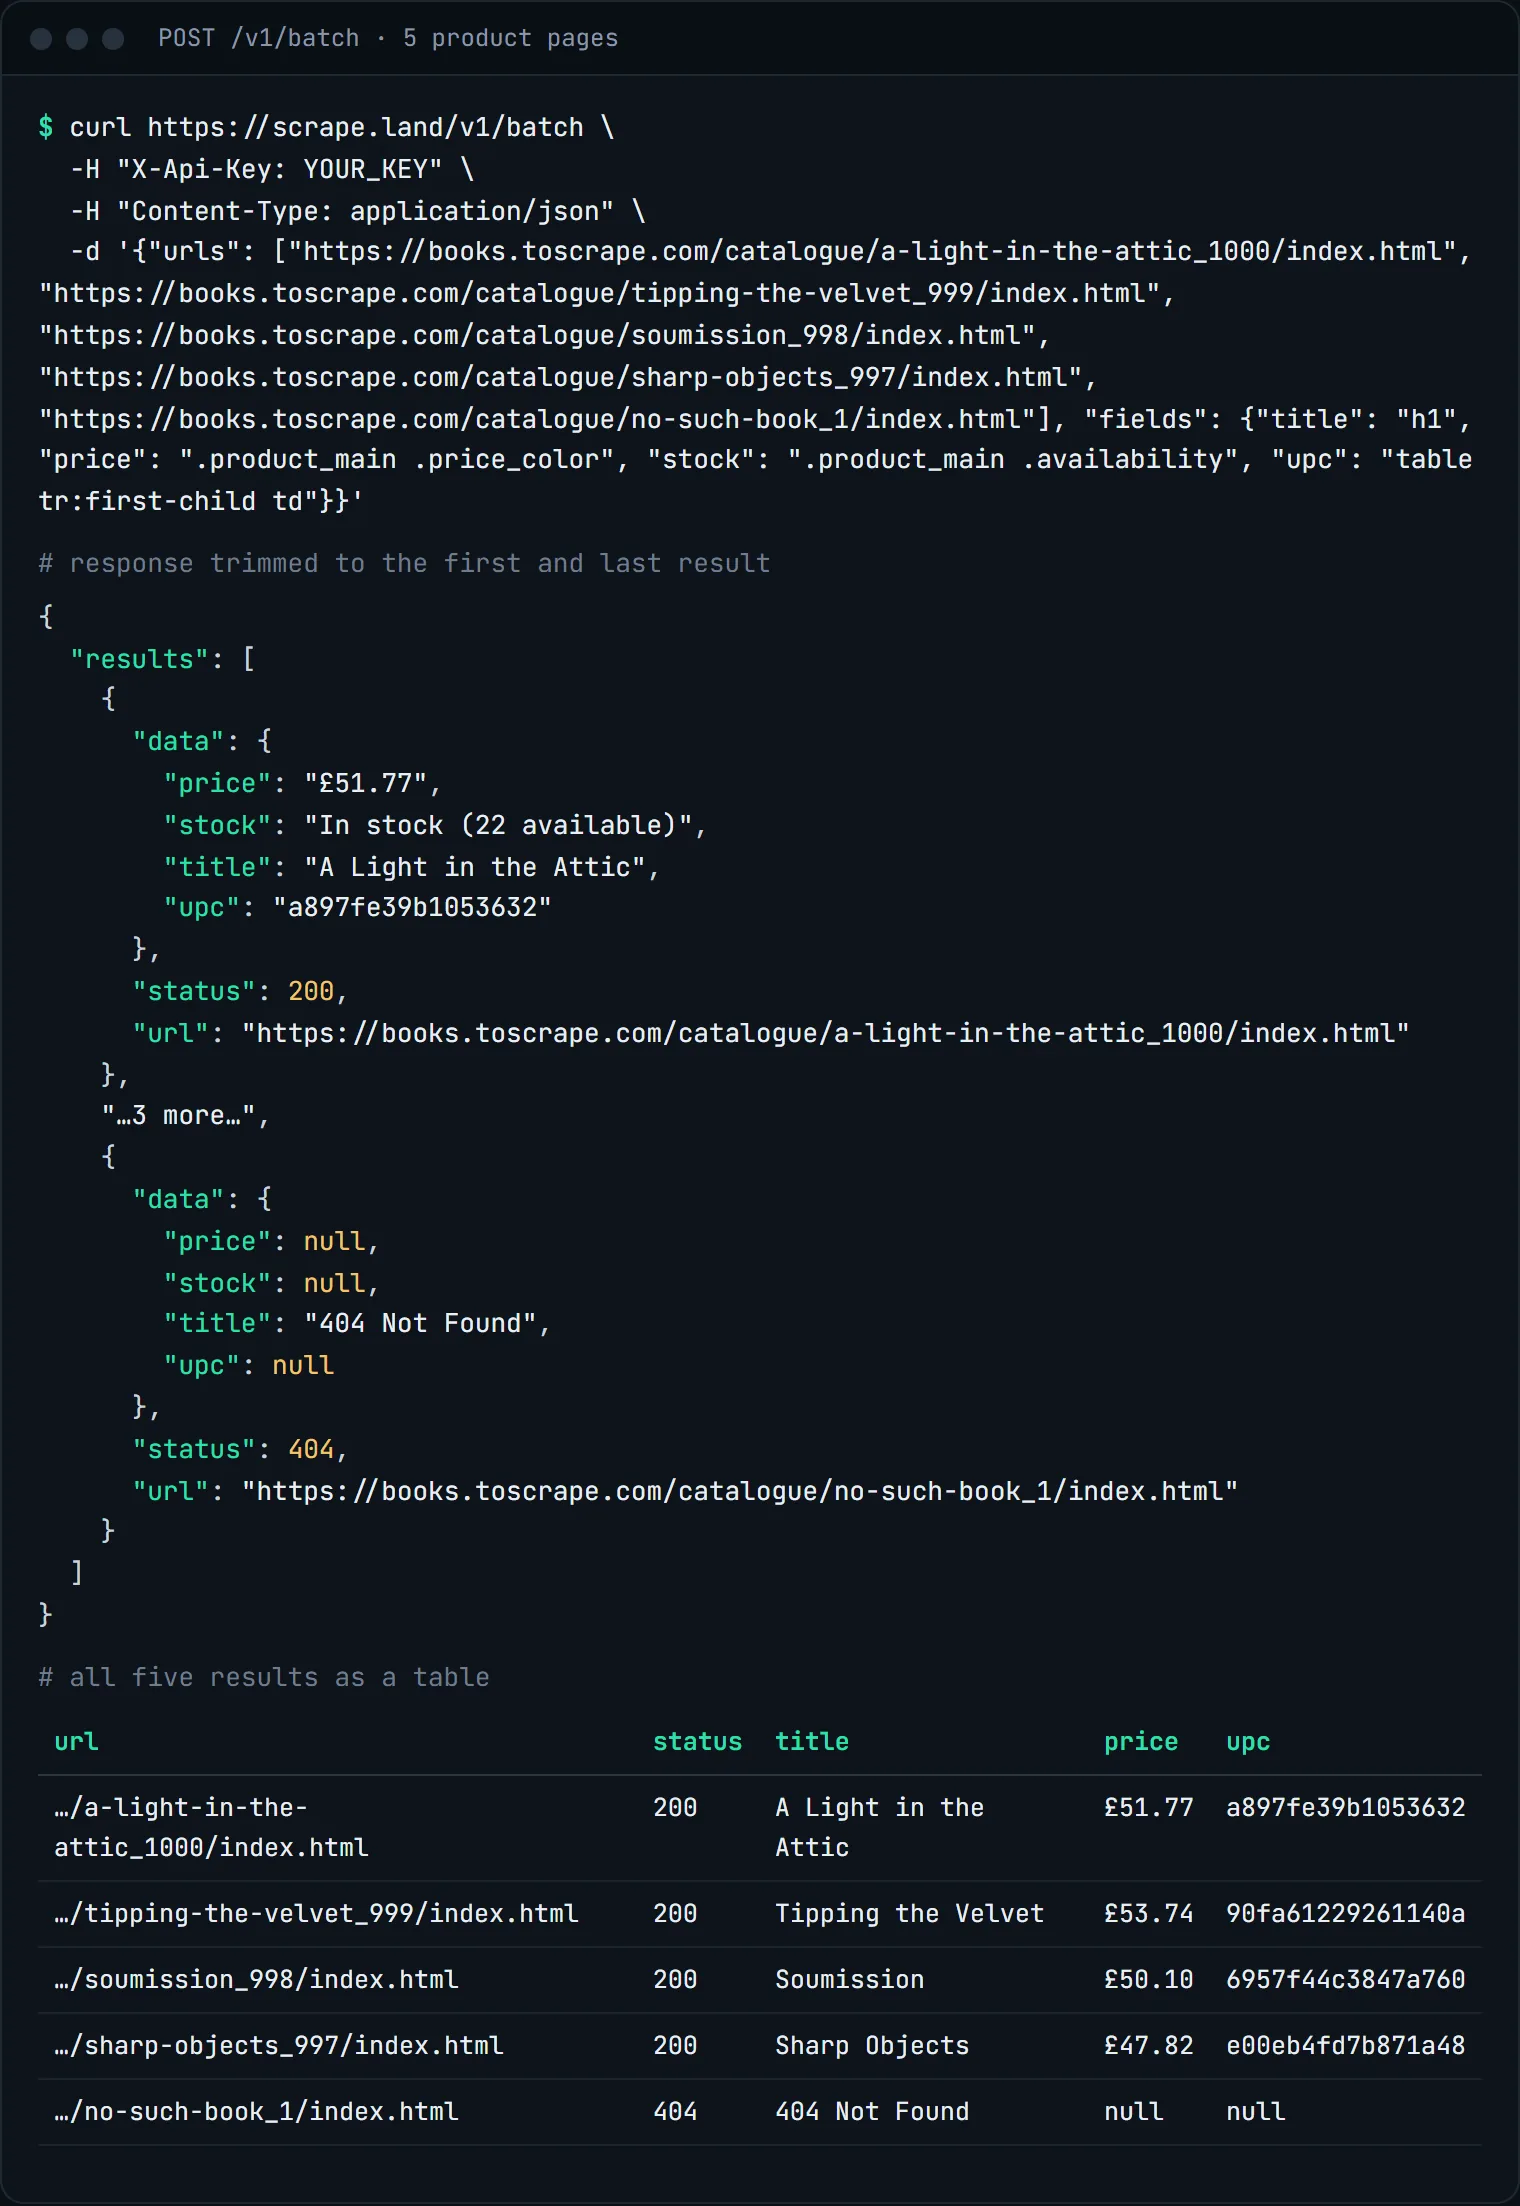 How to batch-scrape many URLs in one call
Send up to 20 product URLs in one request and get the same fields back from each page, in input order.
-
 How to monitor competitor prices on a schedule
Run a small script from cron that extracts each competitor price, appends it to a CSV and flags changes.
-
 How to compare prices across countries
Load one product page from several countries and turn each local price into a currency and a number.
-
 How to scrape product reviews and ratings
Star ratings from class names, review blocks with CSS groups, JSON-LD aggregateRating, and paginated reviews.
-
 How to build a price drop alert in Node.js
A dependency-free Node.js script that checks prices, stores them in JSON and alerts you when one drops.
-
 How to scrape product variants and stock status
Stock text parsed into numbers, sizes and colours from the page's markup, and offers from JSON-LD.
Leads and local businesses
-
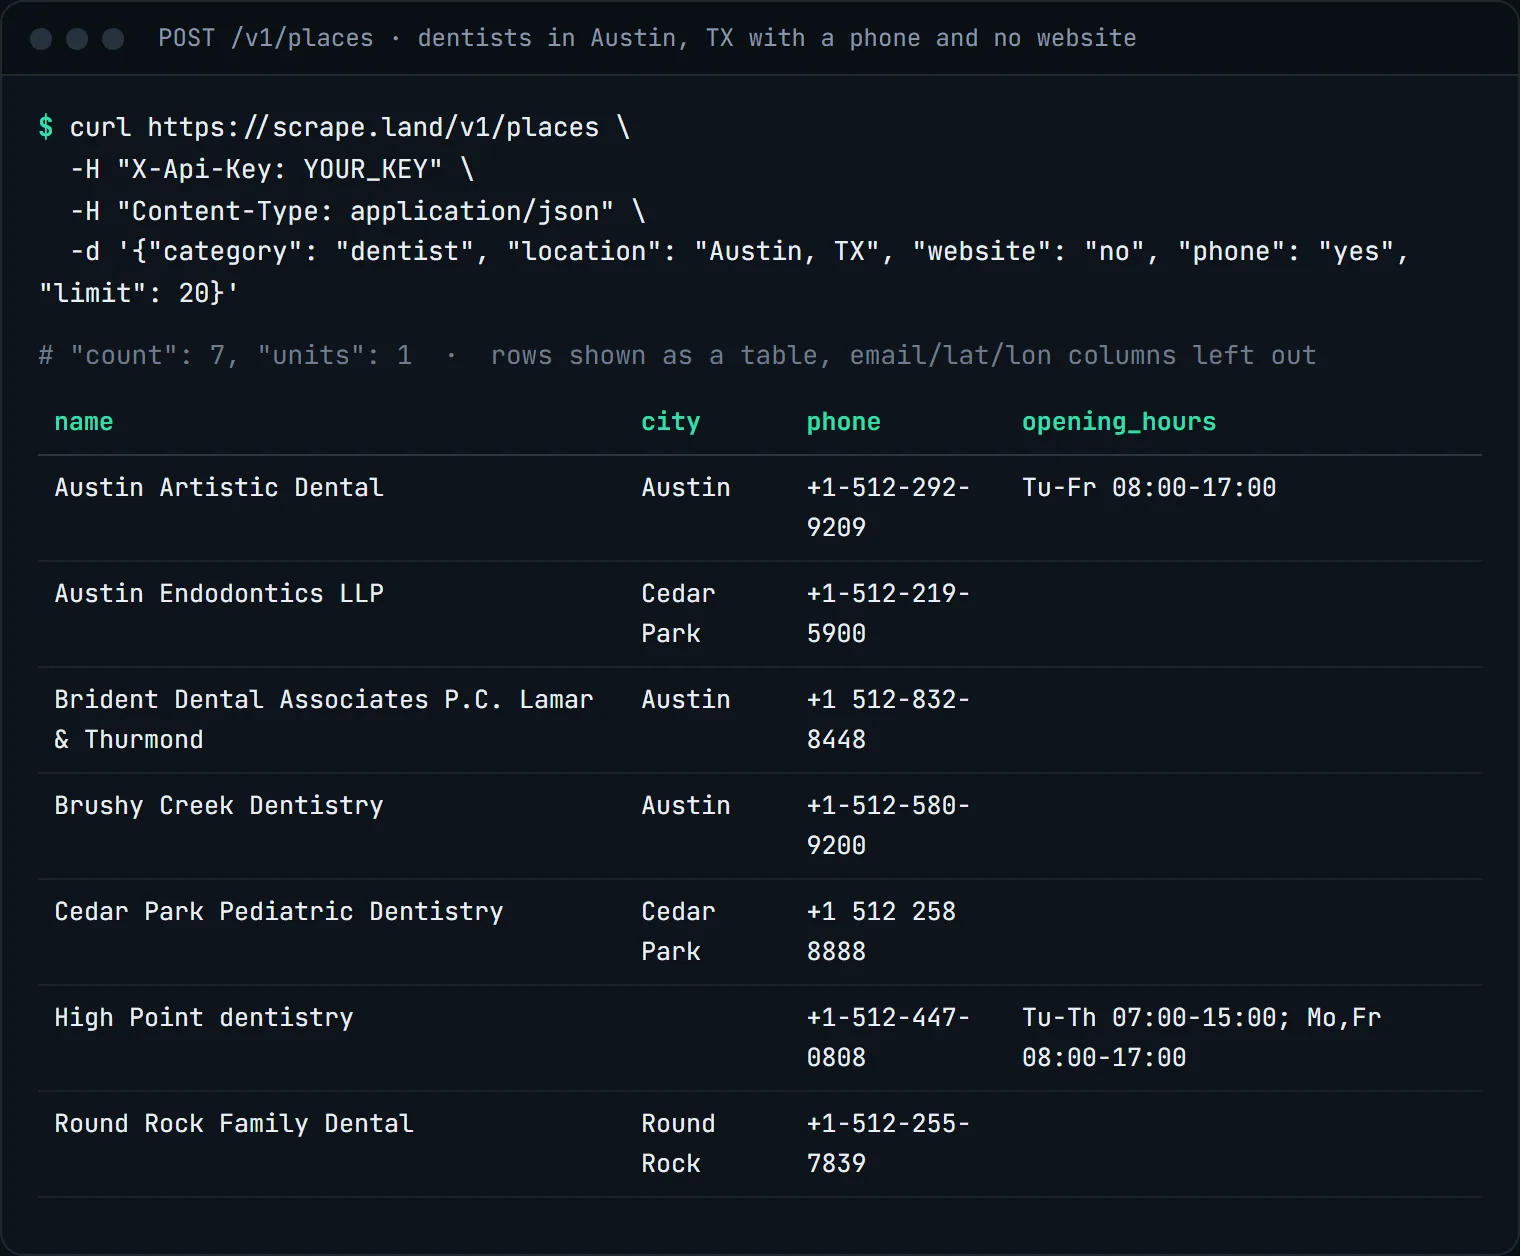 How to find local businesses without a website
List every dentist or plumber in a city that has a phone number but no website, then save it as a CSV.
-
 How to turn a directory page into a lead list
Collect every company link from a directory page, then read the public email and phone from each company's site.
-
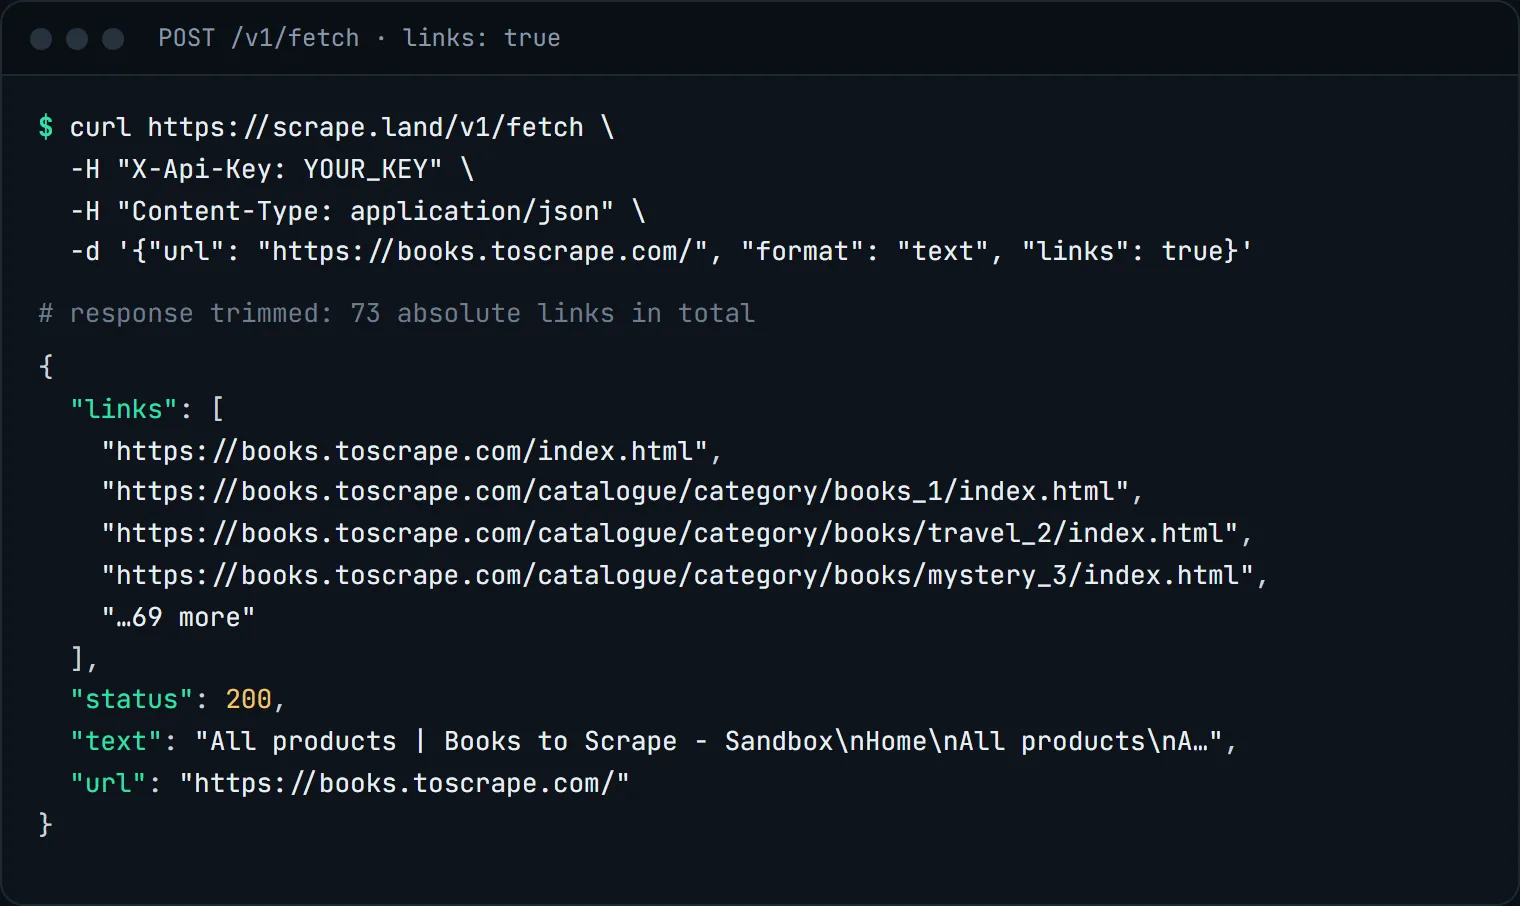 How to extract every link on a page and build your own crawler
Get every link on a page as absolute URLs, then write a small breadth-first crawler with a hard page cap.
-
 How to find restaurants without a website in any city
One /v1/places call lists restaurants with a phone and no website, and explains the profile field.
-
 How to export local business leads to CSV with Python
Loop categories and cities through /v1/places, remove duplicates and write one CSV while counting units.
-
 How to collect contact details from websites in Python
A Python script that fetches each site and its contact page and reads mailto, tel and schema.org data.
-
 How to find B2B prospects by business type and city
Choose categories and cities, filter, enrich, qualify and contact local businesses the right way.
JavaScript and browsers
-
 How to scrape a JavaScript-heavy page
Render a page in a real browser, wait for the element you need, and block images and fonts to keep it at 1 unit.
-
 How to scrape infinite-scroll pages
Render the page, scroll it a few times with short waits, and read every item that loaded along the way.
-
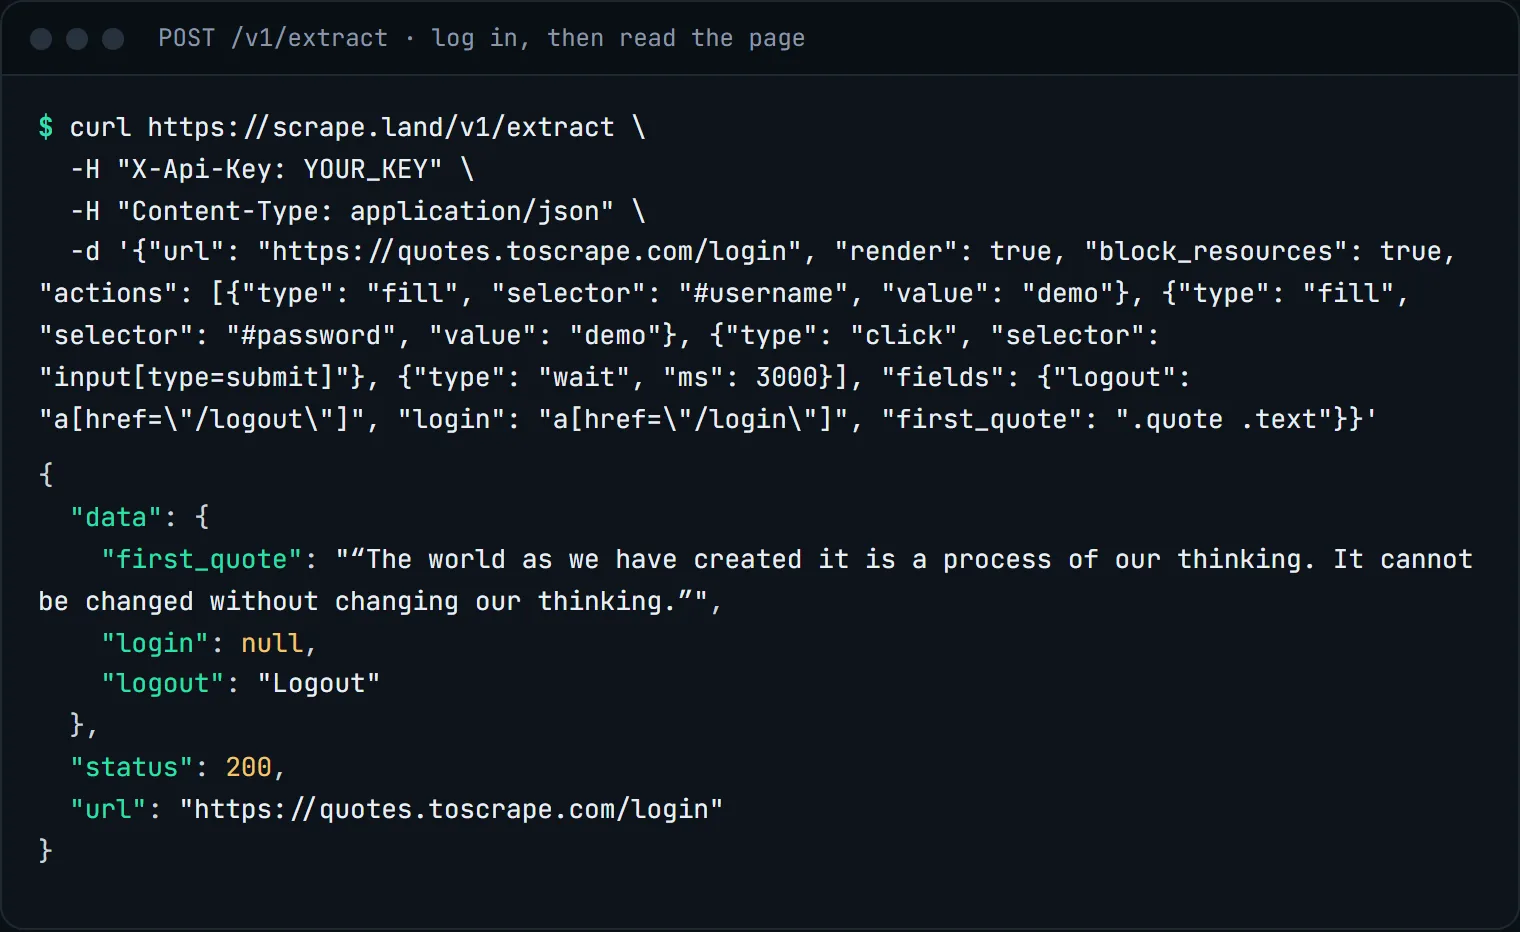 How to fill a form and click a button before scraping
Type into a login form, click submit, wait, and then extract what only a signed-in visitor sees.
Tunneling and IPs
-
 How to rotate IPs and pick a country with tunneling
Point curl or Python at the tunnel, get a new exit IP per request, and choose the country with a suffix on your key.
-
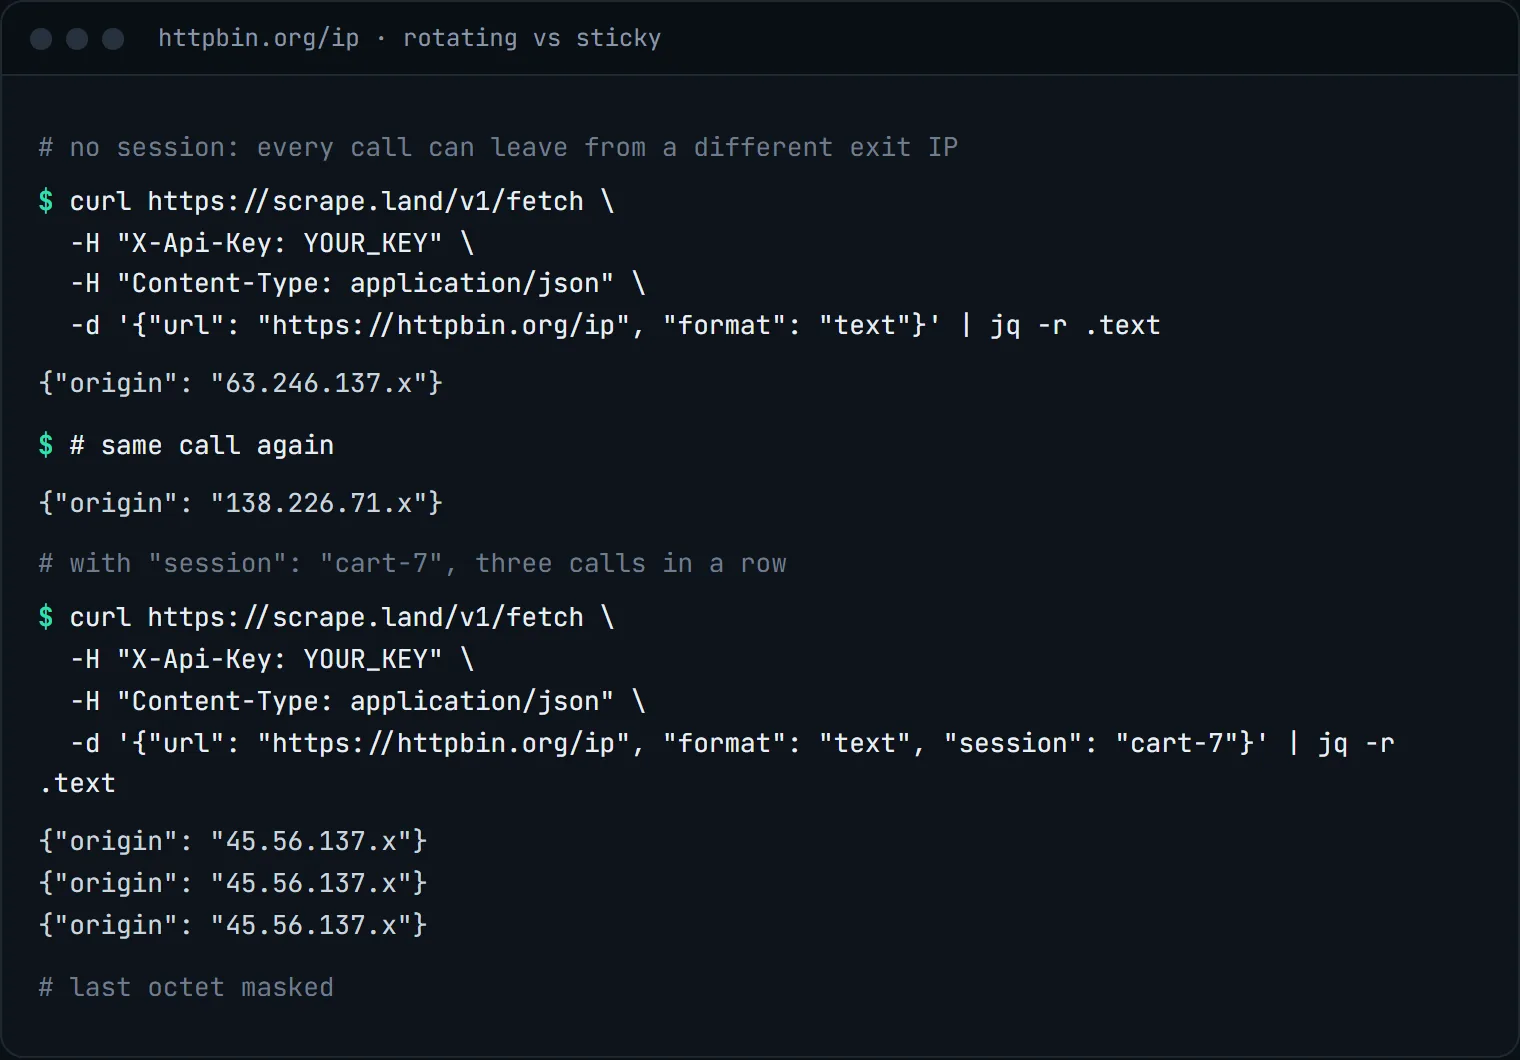 How to keep one IP for a whole session
Name a session and every request that reuses the name leaves from the same exit IP. Rotation is the default.
-
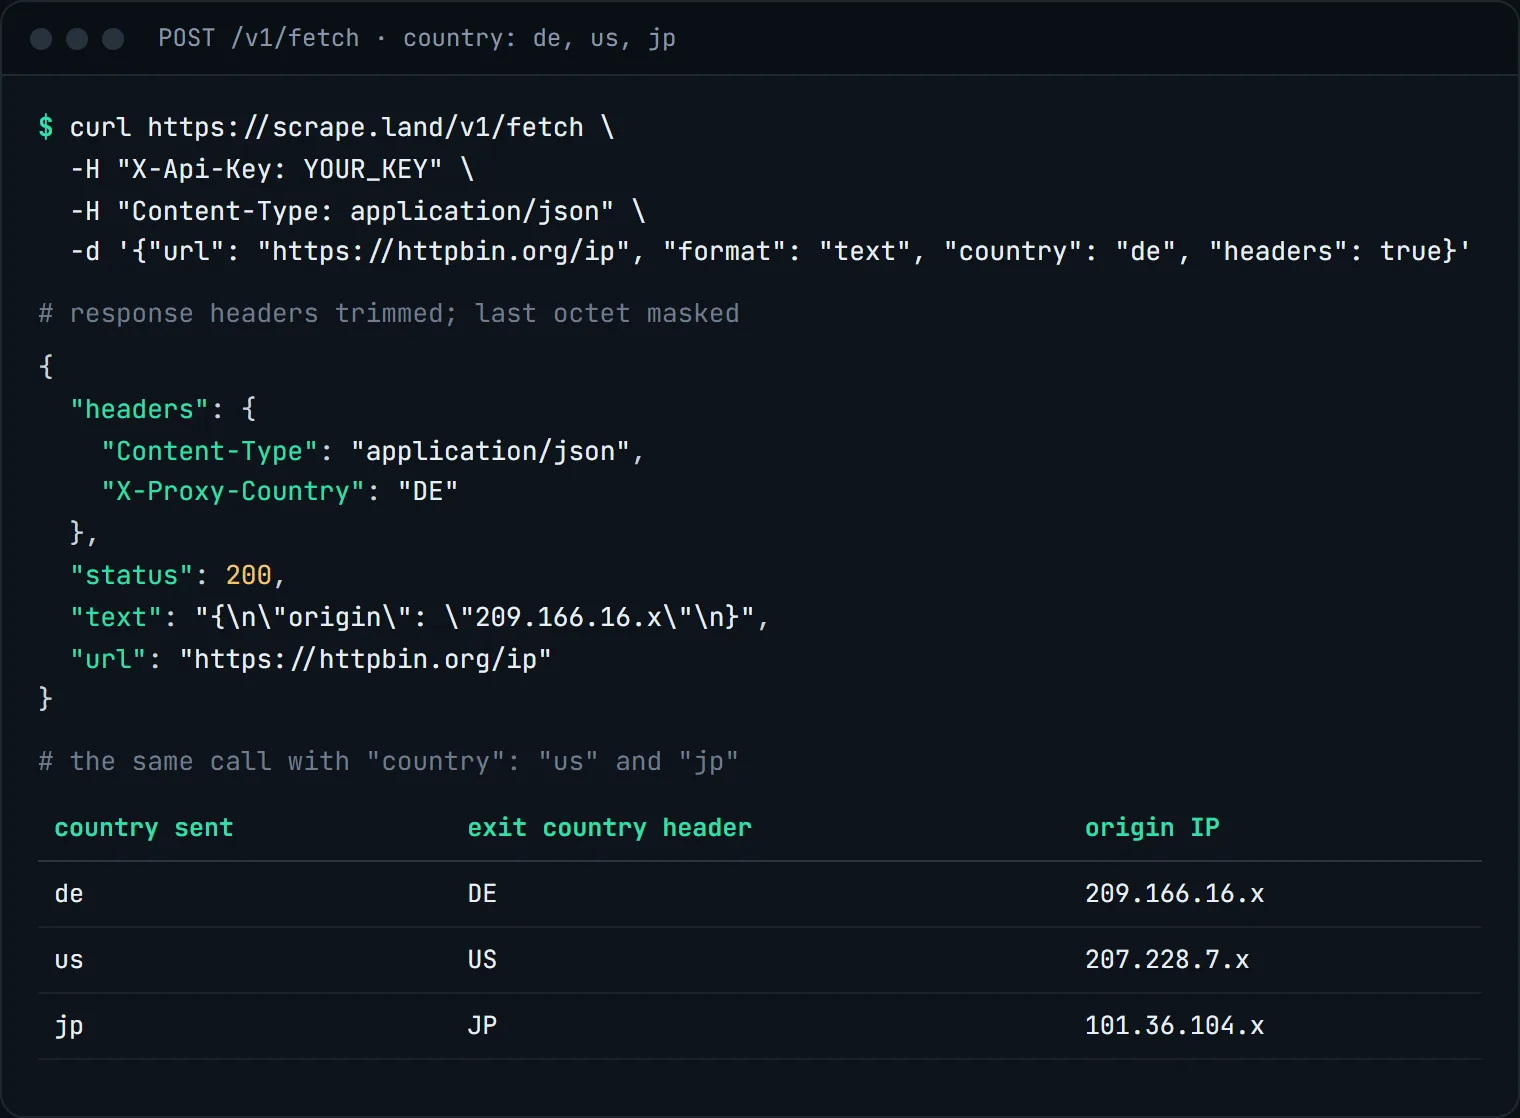 How to get geo-targeted results by country
Set a two-letter country code and the request leaves from that country. Check it, and when to use it.
-
 How to route Python requests through scrape.land
The gateway URL, country and session options, checking the exit IP, and the tunnel errors in Python requests.
-
 How to use scrape.land in Puppeteer and Playwright
Route headless Chrome through the tunnel, keep one IP per session, and know when render mode is simpler.
AI extraction
-
 How to extract structured data with an AI schema
Describe the fields in plain English, pin each type with a schema, and know when a selector is still the better tool.
-
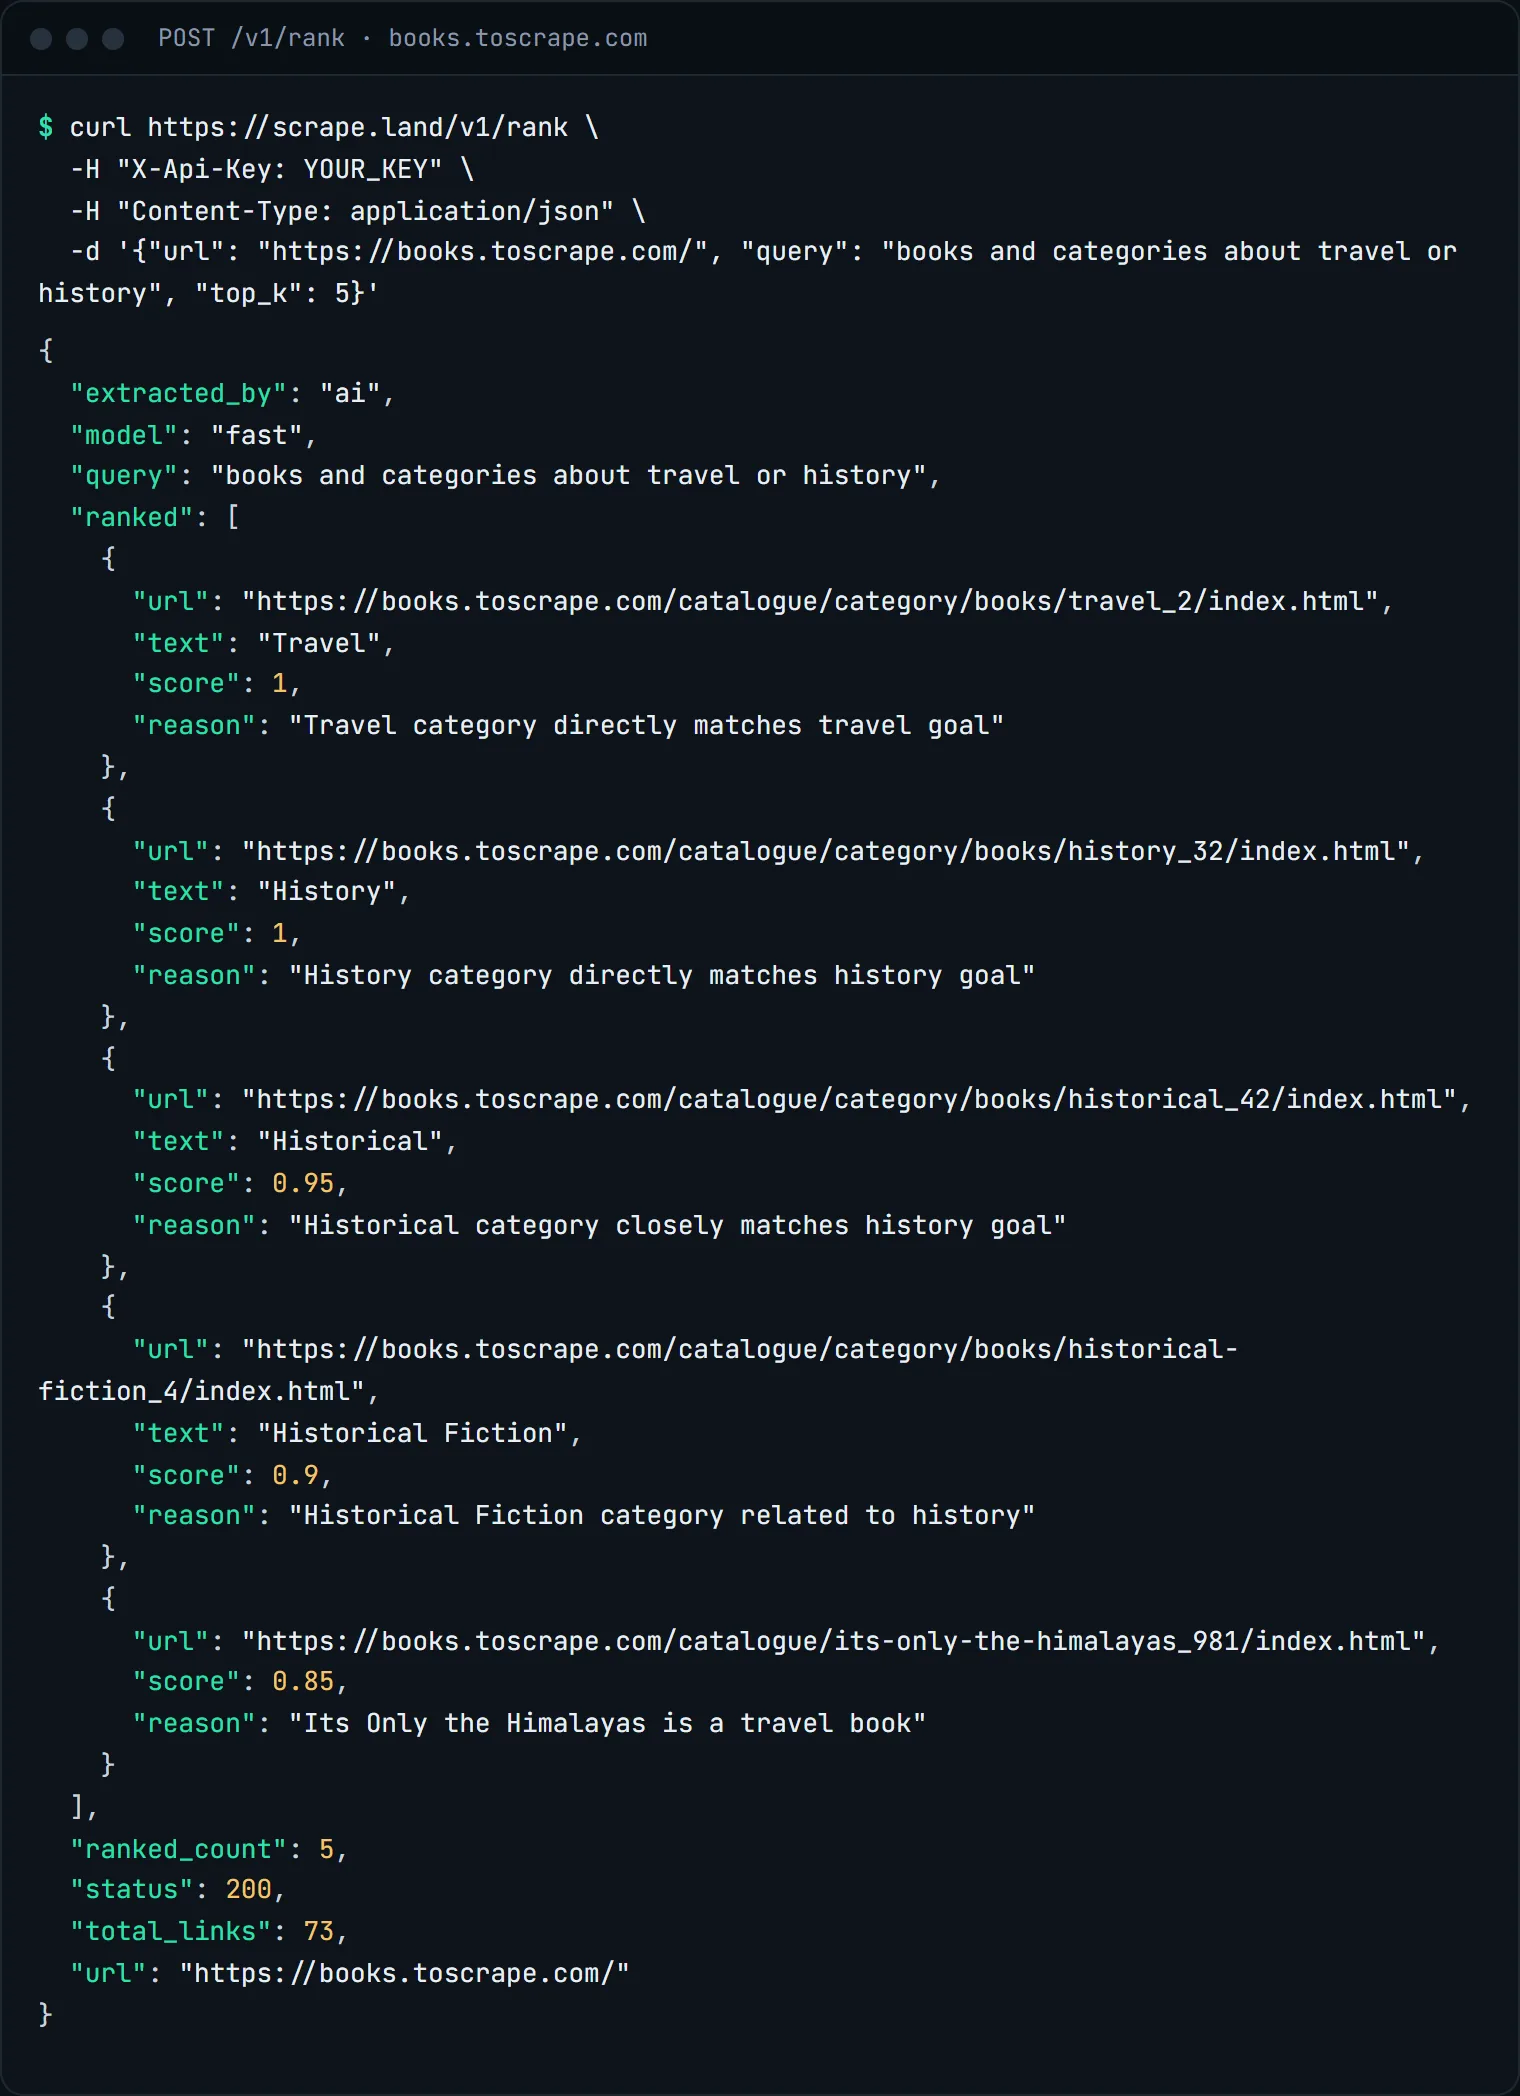 How to rank the most relevant links on a page with AI
Give a page and a goal, get its links ordered by relevance with a score and a reason, then fetch only the top few.
Use cases
-
 How to scrape job listings into a spreadsheet
Job board to CSV: one group request per page for title, company, location and link, following pagination.
-
 How to track real estate listings with a daily scrape
Daily snapshots of a property search, diffed into new, removed and repriced listings, run by cron.
-
 How to scrape news headlines into JSON
Headlines, links and times into JSON with CSS groups, article details from JSON-LD, and no duplicates across runs.
-
 How to watch a web page for changes and get alerted
Hash a field or a page's Markdown on a schedule and send a Slack, webhook or email alert when it changes.
-
 How to scrape event listings into a calendar
Pull titles, dates and venues from an events page and write an .ics file any calendar app can import.
Integrations
-
 How to use scrape.land from Claude and AI assistants (MCP)
Add one MCP server so Claude and other assistants can fetch pages, extract data, search and find local businesses.
-
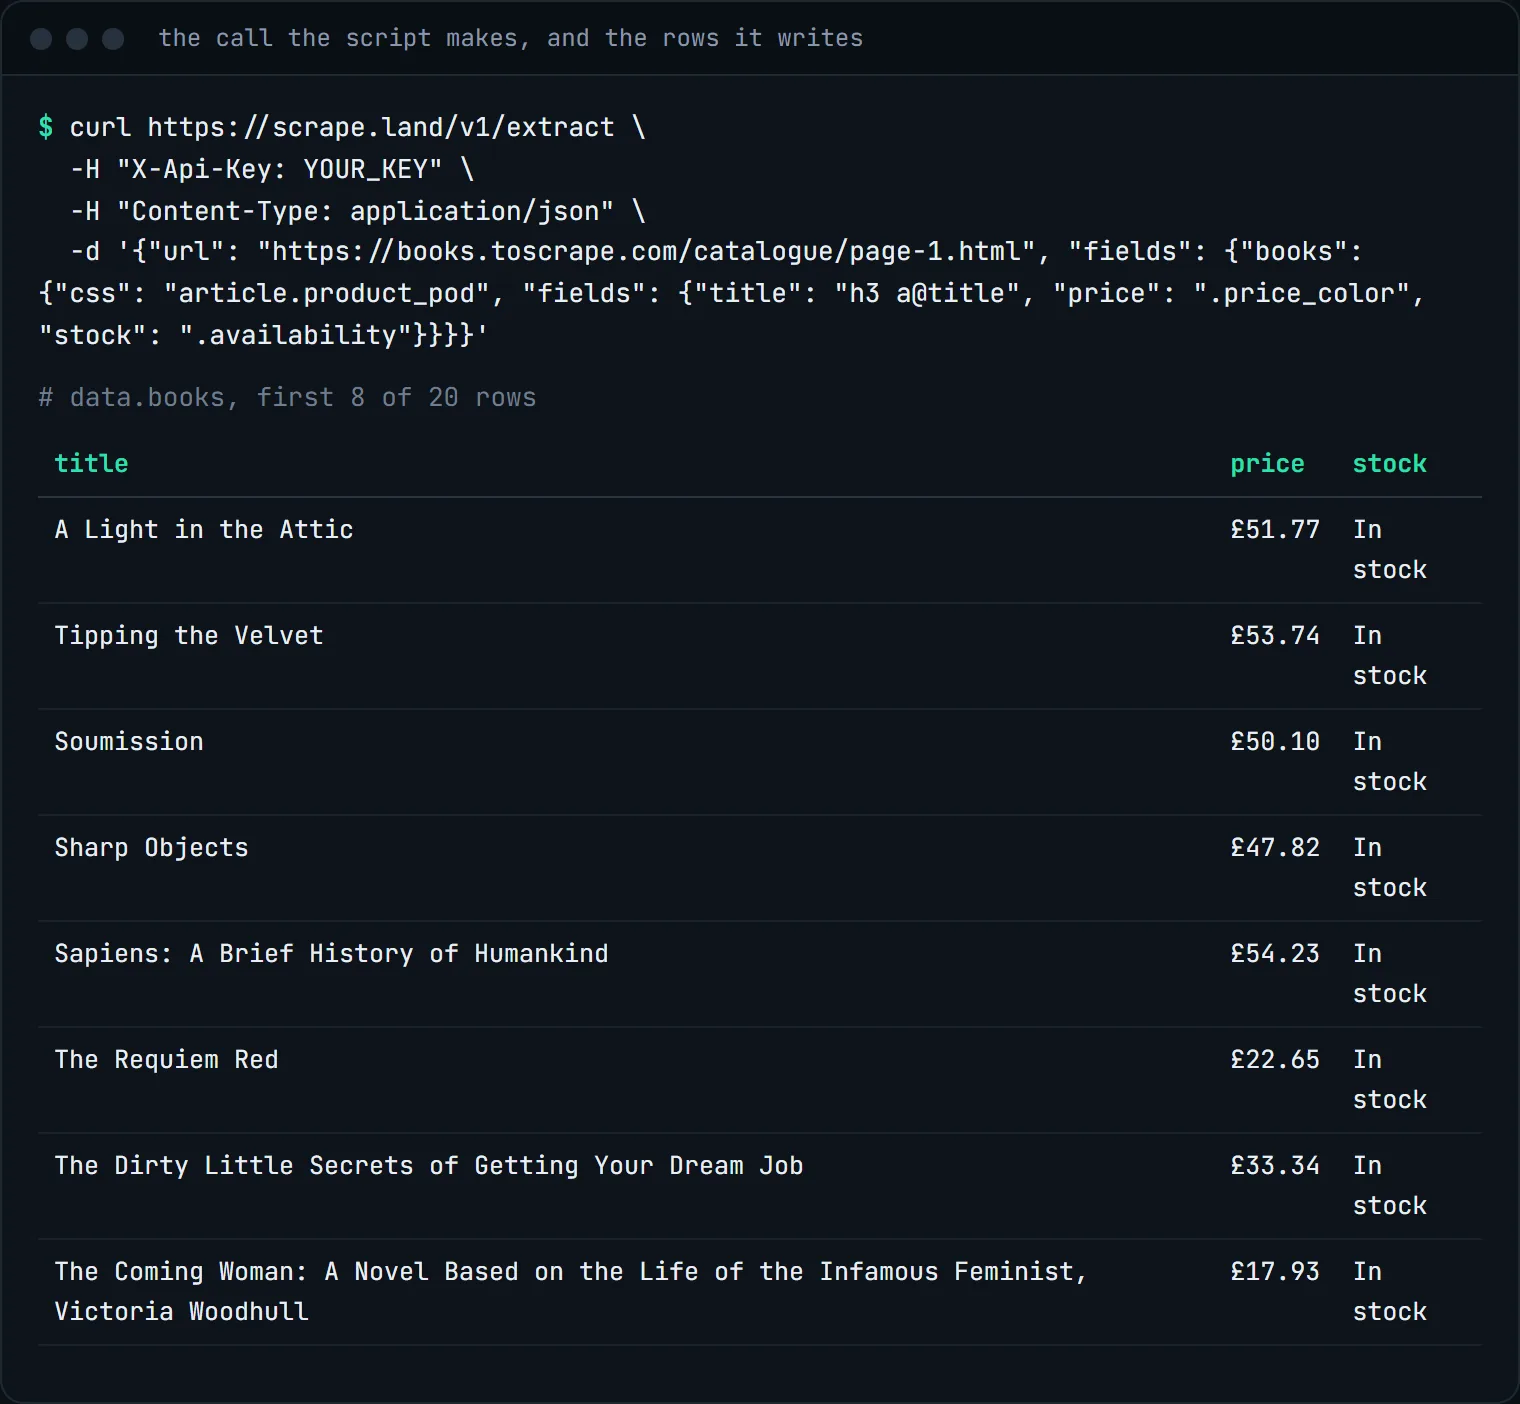 How to pull scraped data into Google Sheets with Apps Script
A short Apps Script that calls the API, writes one row per item into a sheet, and keeps the key in Script Properties.
-
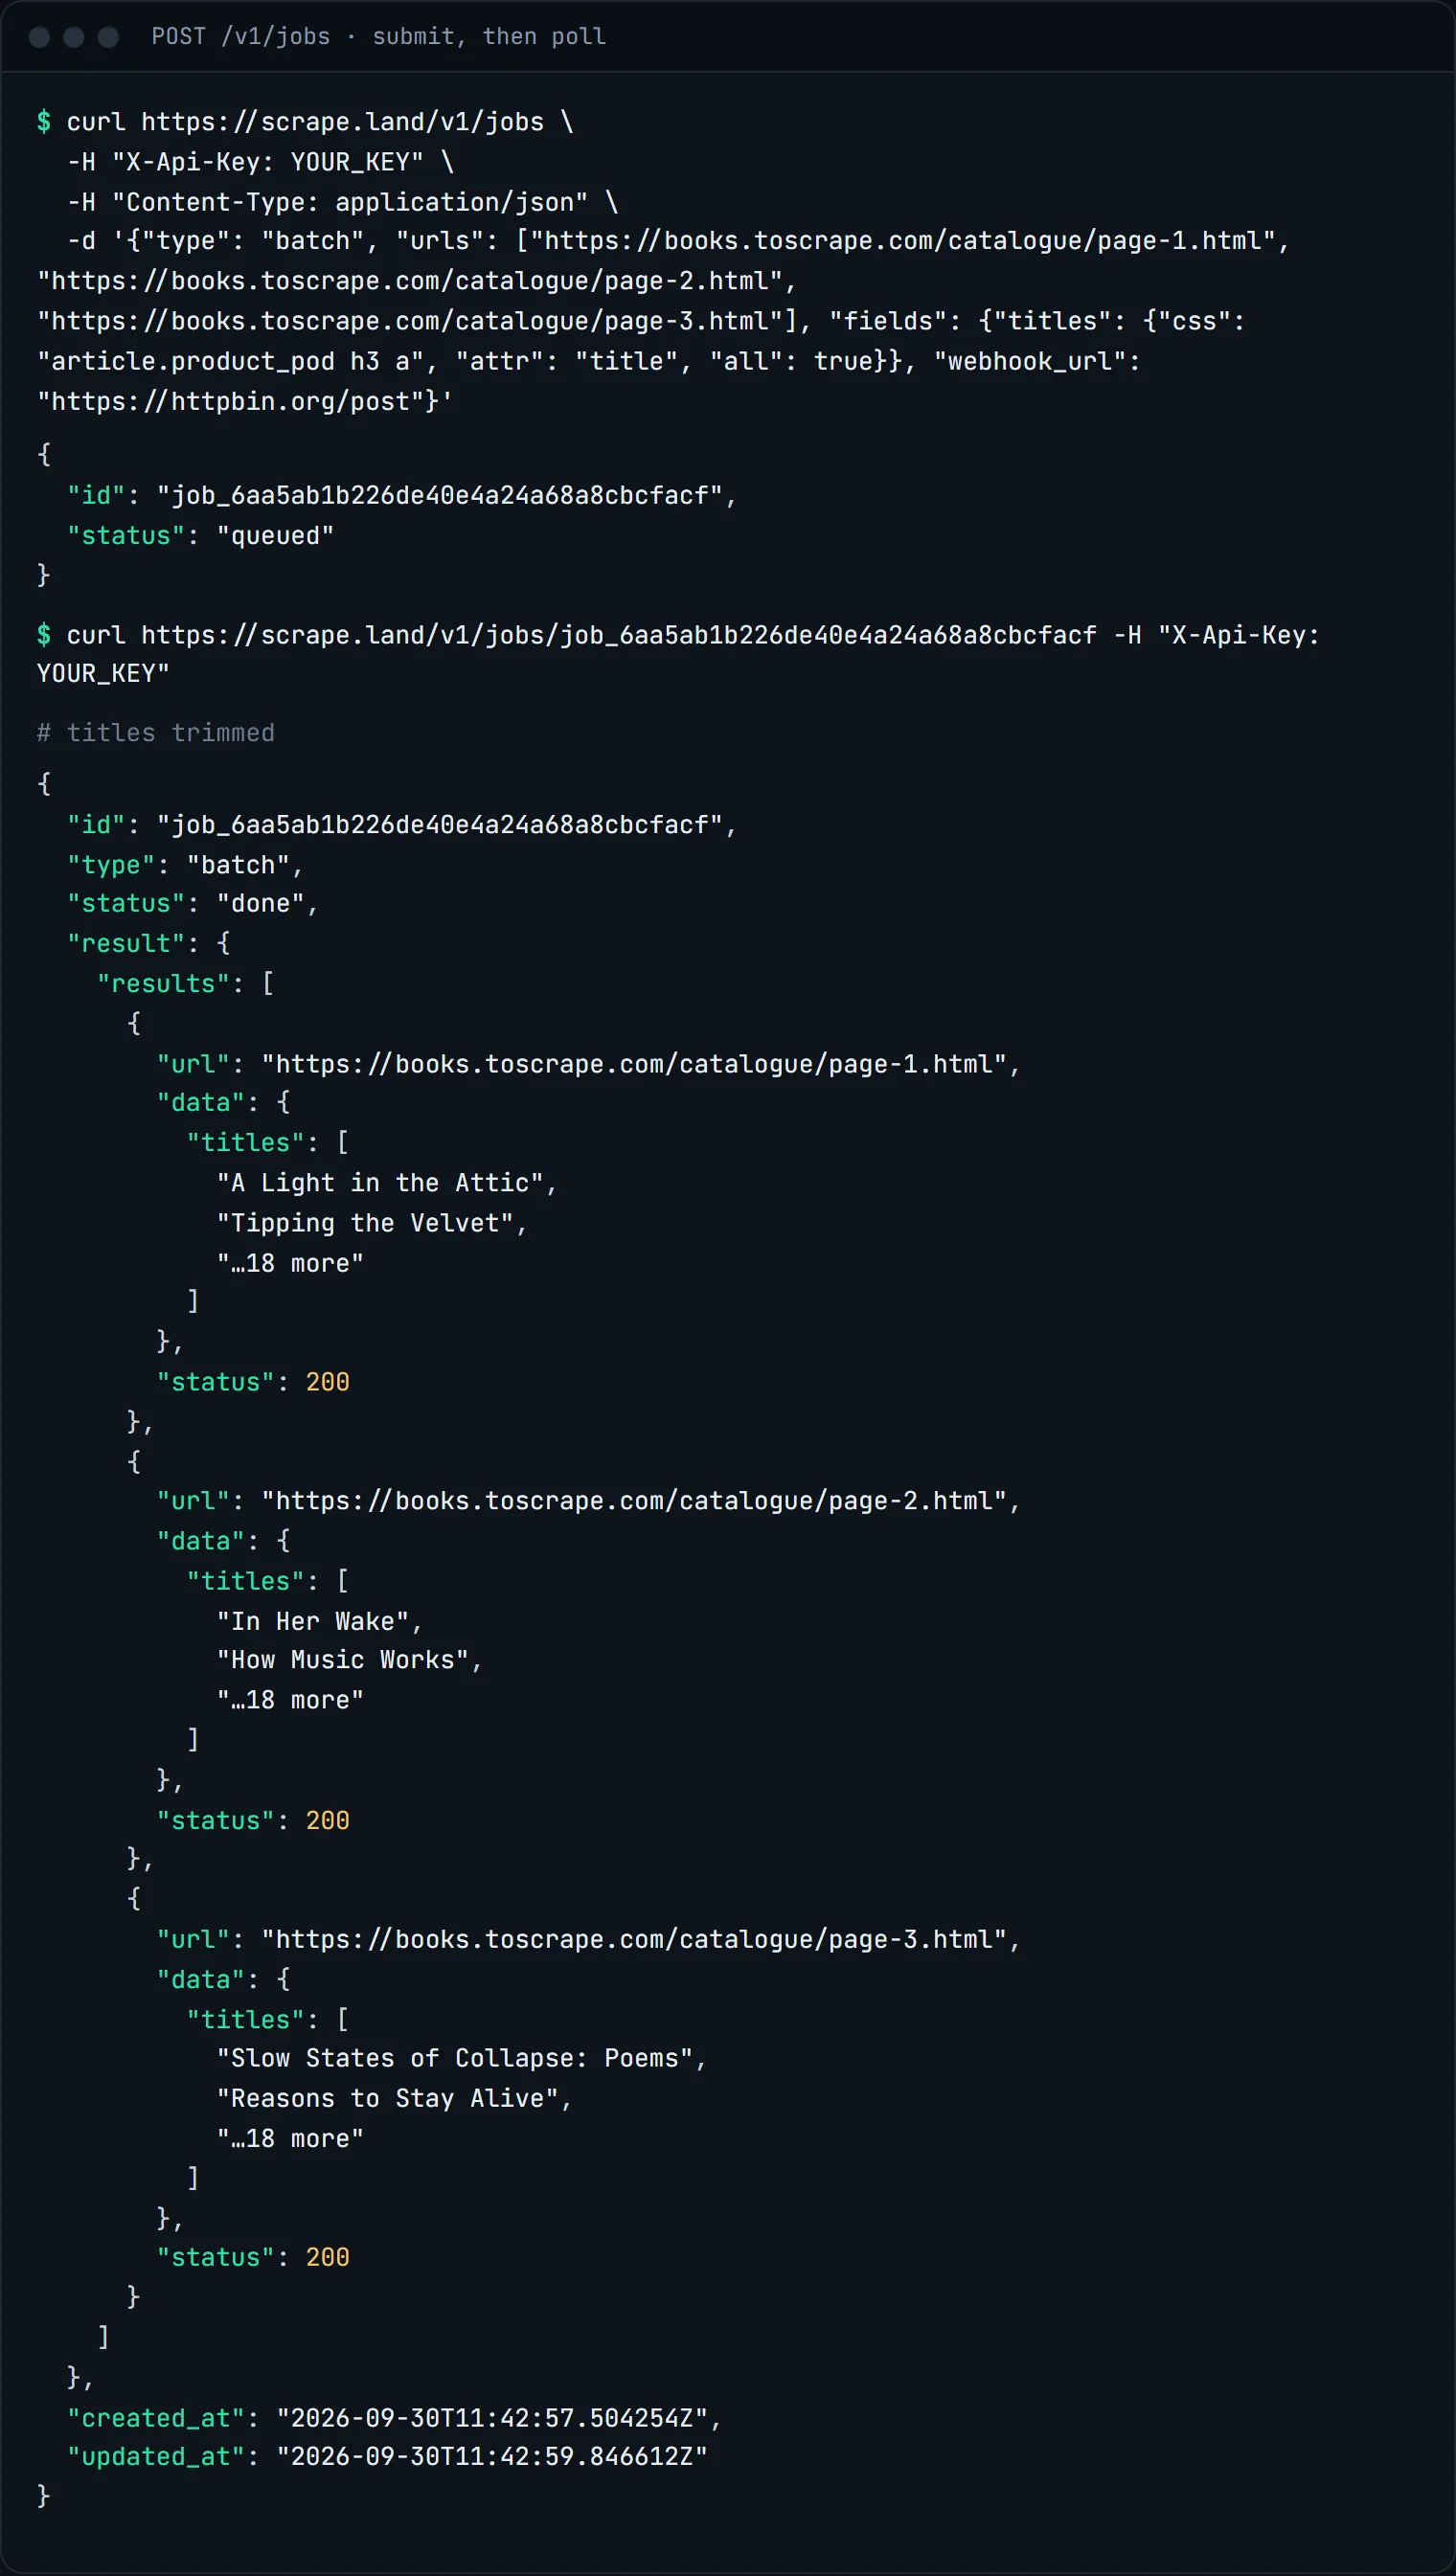 How to run long scrapes asynchronously with jobs and webhooks
Submit a batch as a job, get an id back at once, then poll it or receive the result on a signed webhook.
-
 How to use scrape.land with Scrapy
Send a spider through the tunnel or call /v1/extract from it, with settings that stay inside your plan's rate.
-
 How to scrape websites with n8n, Make or Zapier
The exact HTTP request, field mapping and error handling for n8n, Make and Zapier.
-
 How to find local businesses from Claude with MCP
Ask Claude for florists without a website in Bristol and get real OpenStreetMap rows back through MCP.
Plans and scale
-
 What the $19 unmetered Pool plan is for
What $19 unmetered buys you, what it leaves out, and when a metered plan is the better choice.
-
 How to crawl thousands of pages at 10 requests a second
A threaded Python crawler with a token bucket, 429 handling and resume, tested on books.toscrape.com.
-
 How to cut web scraping costs with block_resources
How units are counted, a render for 1 unit instead of 5, what is never billed, caching, and choosing a plan.
-
 How to choose the right plan for your scraping volume
Worked examples from 300K to 60M requests a month, including when the plan below plus credit is cheaper.